
PuckCast Edge
Every pick is free. The Edge is the rest.
Betting edges, stake sizing, props priced against the line, fantasy tiers and the graded ledger. $14.99 a month in season, or $99 for the year.
PuckCast Edge
Betting edges, stake sizing, props priced against the line, fantasy tiers and the graded ledger. $14.99 a month in season, or $99 for the year.
The Story
A class project that refused to stay in the classroom.
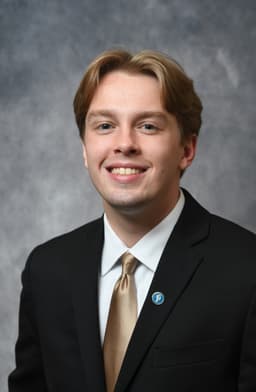
Buffalo, NY · MS Business Analytics, University at Buffalo
I started PuckCast for a sports analytics assignment. Pick a sport, build a model, see what happens. I picked hockey, got to about 59% accuracy, and thought that was actually pretty good for NHL games. So I kept going after the class ended.
More data, better features, five full seasons of validation. The model got sharper. I added a confidence grade from A down to C because not all picks are equal and pretending otherwise is how you lose trust fast. Then I built the site because a model sitting in a notebook doesn't do anything for anyone.
I'm still in school, still building this. I was at the Sabres 8-7 comeback against Tampa this year. No model predicts that, and that's why hockey is fun to try and predict.
Trust the model. Or don't. It's still right most nights.
The Model
Data
16 seasons of NHL game data
Features
158 inputs -- Elo, momentum, goalies, context
Training
Logistic regression, C=0.02
Validation
6-fold walk-forward on 7,428 games
Prediction
Automated daily picks
Track Record
60.7%
walk-forward accuracy
7,428
holdout games tested
+7.0
pts above baseline
0.659
log loss
Walk-forward validation across 6 temporal folds -- no data leakage, no lookahead bias.
Higher grade = more confident = historically more accurate.
FAQ
Fresh predictions go out every morning via automated GitHub Actions. The model pulls the latest stats from the NHL API and recalculates all 98 features before making picks for the day's slate.
No. PuckCast is an analytics platform. We don't sell picks, offer betting advice, or take a cut of anything. Sign in for free predictions and analytics, or upgrade to Pro for full access.
Yes. The full codebase — model training, feature engineering, and website — is on GitHub. You can inspect everything.
v2.0 en95+trend runs a single logistic regression with C=0.02 regularization. We tested ensemble approaches and gradient boosting, but the simpler model generalized better on ~6,500 games of training data. The edge comes from feature engineering (98 features including multiple Elo variants, rest/fatigue detection, and rolling performance windows), not model complexity.
The model is trained on past seasons and tested on future ones it's never seen -- no peeking. We use 6-fold walk-forward validation across 7,428 games, so the 60.70% accuracy reflects real predictive power, not overfitting to historical data.